Ain't No Mountain High Enough Trend: AI Subway Singing Video
Picture this: an empty subway, white wired headphones, eyes shut, one hand raised high as you sing like no one's watching. Upload one photo of you or your pet, then get your selfie video.
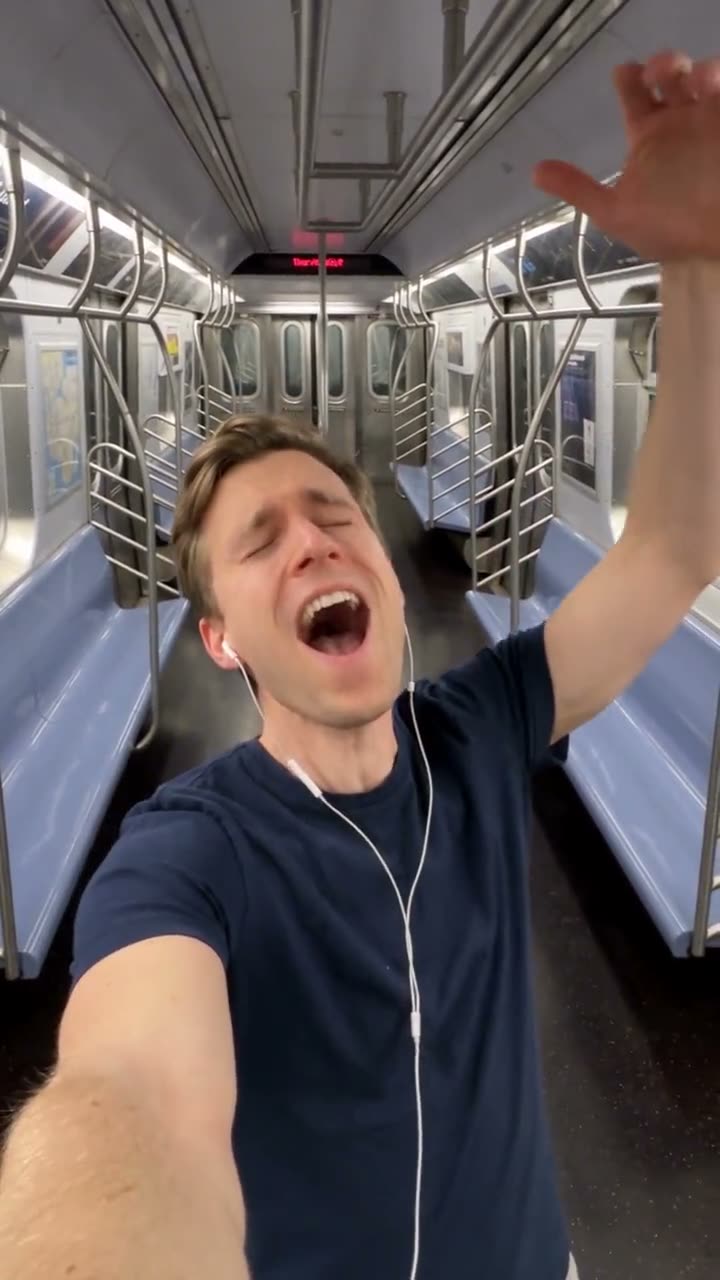
The Ain't No Mountain High Enough trend shows a selfie moment: sitting by yourself in an almost deserted subway car, white wired headphones on, you shut your eyes, throw up one hand and sing the 1967 soul hit. Smew AI creates your 10-second clip from a single photo, or places your pet in the seat to perform.
Also called Ain't No Mountain subway singing · Subway singing trend · Singing on the subway with earphones
Step by step
How to make the Ain't No Mountain video on Smew AI
It all happens in your browser. No editing software needed, no prompt writing, no watermark added.
Upload your photo
Tap "Create your own" and upload your image, showing your face clearly (chest up). Snap it with your camera or select from your library.
Tap Generate
The cost shows on the button. Seedance 2.5 creates the Ain't No Mountain scene directly from your photo, no intermediate image, producing 10 seconds with original audio. No prompt needed.
Download or share
Your video arrives in minutes as a 9:16 MP4. Save it, share from your device, or access it later in your Library.
Which photo works best?
You'll need one photo: yourself for Human mode, your pet for Pet mode.
Human: a clear image from chest upward, looking at the camera, well-lit, similar to a selfie. Hair, face and clothing in the final video match this image, with white wired headphones added automatically.
Avoid sunglasses, masks, hats covering eyes, and beauty filters. Make sure no one else appears in the frame.
Pet: a single animal with visible face and ears; seated position works best. Works with both dogs and cats. Headphones appear in your pet's ears in the video.
This template is for adults and pets. Upload yourself, a consenting adult, or your own pet. Never use images of children, celebrities or strangers.
Where did the Ain't No Mountain trend start?
"Ain't No Mountain High Enough" is the soul duet Nickolas Ashford and Valerie Simpson wrote for Marvin Gaye and Tammi Terrell, which came out in 1967; Diana Ross made her own recording in 1970. The chorus remains one of pop music's most sung lines, and the song is trending again on TikTok in October 2026: #aintnomountainhighenough shows 18,357 videos with 247.5 million views (20 October).
The subway version captures an everyday situation: forgetting others in the car can hear you as you sing to your headphones. Sitting by yourself on a bench, white cable across your chest, the performer holds a hand to the ear phone-style, shuts their eyes, tilts their chin upward and raises one hand high during sustained notes. On 18 October 2026 an AI video site shared what appears to be the earliest AI version we could locate: transforming one photo into a woman singing in the subway. On 20 October two AI template sites introduced it as a single-photo template. The original real-person reel hasn't been identified yet (we searched TikTok and the song's audio page on 20 October); we'll update here once we locate it.
Marvin Gaye and Tammi Terrell release "Ain't No Mountain High Enough", written by Nickolas Ashford and Valerie Simpson.
An AI video site shares what appears to be the earliest AI version we found: transforming one photo into a woman singing in the subway with wired headphones.
Two AI template sites introduce an "Ain't No Mountain subway singing" template that generates from one photo.
#aintnomountainhighenough shows 18,357 TikTok videos with 247.5 million views; #subwaysinging shows 195 videos with 4.8 million views. TikTok
Copy and paste
The Ain't No Mountain prompts
You won't need these: the single-tap workflow handles it automatically. [Image 1] is your uploaded photo: the video model uses it as reference and creates the scene directly, without generating a photo first.
Human
1 photo: you, face clear (chest up)Seedance 2.510 s · 720p · 9:16126 credits
Video prompt
A realistic vertical phone selfie of the person in [Image 1], seated in a nearly empty subway carriage, wearing wired earbuds. They sing passionately to a soulful chorus, close their eyes, lift their chin, raise one hand, and move their lips naturally. Preserve their face and hairstyle, keep the train background consistent, subtle handheld camera movement, emotional expression, cinematic realism, 9:16.
The singer is the person in [Image 1], in every frame: copy the exact face from [Image 1] (the face shape, eye color and eye shape, eyebrows, nose, mouth, skin tone, age, hair color, hair length and hairstyle, and any beard, moustache, glasses or freckles), and the clothes from [Image 1], so their friends recognize them at once. The face stays the same from the first frame to the last, also with the eyes closed, the chin up and the mouth wide open on the long notes. Never morph. If [Image 1] shows an animal, the singer is that animal sitting upright on the seat, with its own face, fur and markings, not a person.
The place: the inside of a clean, nearly empty city subway car at night under bright white ceiling lights: long blue bench seats along both walls, steel grab poles and handrails, sliding doors, a framed route map on the wall with no readable words, the car stretching away behind, dark windows with lights flicking past. The train sways softly.
The camera: their own front phone camera in one outstretched hand, a little above eye level, a medium close-up from the chest up, one continuous take with no cuts; the face stays big and sharp. Thin white wired earphones in both ears, the white cable hanging down over the chest.
0-2 s: eyes on the lens, a small smile; they hold the other hand to the ear like a phone, thumb and little finger out: call me.
2-4 s: they close their eyes, tip the head back and start to sing out loud with feeling.
4-7 s: the other hand rises high above the head, fingers spread, the chin lifted, the mouth wide open on a long held note; they sway with the train.
7-10 s: they open their eyes, look straight into the lens and sing the chorus right at the camera, the other hand reaching out with an open palm, then a big happy smile.
Audio: only their own voice, a big, soulful chorus with long held notes, a little off-key, over the low rumble and clatter of the train. No instruments: the music plays only in their earphones.
Exactly one person in the car, no other passengers. One head only, two arms, five fingers on each hand. No phone visible in the frame. No text, no subtitles, no logos, no line names or route numbers, no watermark.
1 photo: your pet, face clearKling 3.010 s · 1080p · 9:1656 credits
Video prompt
Use the uploaded image as the base. 9:16 vertical photo, like a real phone selfie taken close in front of the pet, at its eye level. The pet from the uploaded image sits upright alone on a blue bench seat in the inside of a clean, nearly empty city subway car at night under bright white ceiling lights: long blue bench seats along both walls, steel grab poles and handrails, sliding doors, a framed route map on the wall with no readable words, the car stretching away behind, dark windows with lights flicking past. A medium close-up from the chest up, the face big and sharp, looking into the lens. Thin white wired earphones sit in its ears, the white cable hanging down over its chest. Realistic photo with natural colors. Exactly one animal and no people. No clothes on the pet. No phone visible, no text, no logos, no line names or route numbers, no watermark.
Payment is per video in credits, with the exact cost displayed on the Generate button before any charge. The single-tap price includes both scene photo and video, billed once. Each mode has separate pricing: Human 126 credits, Pet 56 credits. Lower-cost models are available if you manually run prompts in AI Video.
Video model
Settings
Credits
Human: Seedance 2.5 (this template)
10 s, 720p, straight from your photos, one tap
126
Pet: Kling 3.0 (this template)
10 s, 1080p + 1 scene photo, one tap
56
One-time packs and plans are on the pricing page. A failed video gives its credits back.
What happens in the Ain't No Mountain subway singing video?
One continuous selfie shot of about 10 seconds, vertical 9:16, in a clean, nearly empty subway car at night:
Time
Human
Pet
0-2 s
You look into the lens with a small smile and hold a hand to your ear like a phone: call me.
Your pet sits on the bench seat with the white earphones in, looking into the lens.
2-4 s
You close your eyes, tip your head back and start to sing.
It closes its eyes, lifts its chin and starts to sing.
4-7 s
One hand goes up high, fingers spread, the mouth wide open on a long note, swaying with the train.
One front paw goes up, the head tips back on a long note.
7-10 s
You open your eyes and sing the chorus straight at the camera, one hand reaching out, then a big smile.
It sings straight at the camera, then looks into the lens, very pleased.
Human is made straight from your photo, with no in-between picture, so the face stays yours. Pet first places your pet on the subway seat with the earphones in a picture, then turns that picture into the video. Both use top-quality AI video models, including Seedance 2.5; Pet also has a cheaper Standard option and a Best option. The exact price shows on the Generate button before you spend anything, and every run is a new take.
Which sound goes with the subway singing clip?
Your clip includes its own audio: your voice performing a powerful, soulful chorus over train rumble, capturing how it sounds when someone sings to their headphones. The actual song recording isn't included, since the music in the trend only the singer hears through their headphones.
To share it with the song, select "Ain't No Mountain High Enough" from the TikTok or Instagram audio library when posting and lower your clip's original volume. Mouth movements sync with the singing in the clip, matching closely to the chorus though not frame-perfect lip sync. The song is owned by its rights holders, and Smew AI grants no rights to it.
Hashtags: #aintnomountainhighenough (18,357 TikTok videos, 247.5 million views on 20 October 2026), #aintnomountain (1,333 videos), #subwaysinging (195 videos) and #wiredheadphones (25,413 videos). Leave the platform's AI label visible.
Singing pets: can my dog or cat do the subway trend?
Absolutely. Choose Pet mode and upload one image of your dog or cat. Your pet appears seated on the bench in the empty car wearing white headphones and performs passionately: extended, soulful howls from a dog, prolonged sung meows from a cat, eyes shut and one paw raised. This is the singing pets angle of the trend: an AI dog singing or AI cat singing clip. People search "make my dog sing" for precisely this; no actual dog performs on command, but this one will.
Choose Standard for lower cost or Best for the more powerful video model; both create the same initial image of your pet on the seat. For additional pet singing options, explore the singing dog or I Wanna Love You templates.
What goes wrong, and how do you fix it?
Problem
Fix
The face looks less like you with the eyes closed or the head tipped back
Upload a sharp, forward-facing image from chest up in good lighting. Try again: each run produces different results.
A hand has odd fingers on the raised hand
Try another run; an image with your hands outside the frame can help.
A second passenger shows up in the car
The prompt specifies an empty car. Generate again.
The earphones are missing on your pet
Select Best, or try again with an image showing both ears clearly.
The singing does not match the song you add
The clip performs its own chorus; it matches the rhythm closely but isn't frame-perfect lip sync. Lower your clip's volume when posting with the song.
The video model refuses the photo
Certain images get rejected. Credits are returned; upload a different photo.
FAQ
Ain't No Mountain trend questions
What is the Ain't No Mountain High Enough trend?+
It's a selfie video trend: a person sits by themselves in a mostly empty subway car wearing white wired headphones and performs "Ain't No Mountain High Enough" aloud, eyes shut, chin raised and one hand up, acting like no one's listening. AI template sites introduced it as a single-photo template on 20 October 2026, and Smew AI generates your version from one photo.
How do I make the ain't no mountain subway singing video with AI?+
Tap "Create your own", select Human mode and upload one clear photo of yourself from chest up. Tap Generate; the cost displays first on the button. You receive a 10-second vertical selfie video of you performing in the empty subway car with wired headphones. No prompt writing or CapCut template required.
Can I make an AI singing video from a photo?+
Yes. This template functions as an AI singing video generator from one photo: it produces the complete clip, the subway car, the headphones, the movements and the vocal performance, all from your image. You film nothing. It's a complete AI singing video from photo, designed specifically for this trend.
Is there an app for the subway singing AI trend?+
No AI singing video app is necessary: Smew AI operates in your browser on mobile or desktop. Upload your photo, tap Generate, and save the MP4 to share on TikTok or Instagram.
Who started the ain't no mountain high enough tiktok trend?+
That remains unclear. The earliest AI version of the subway take we located was shared on 18 October 2026 by an AI video site, with two AI template sites introducing the template on 20 October. Their example appears to be an AI recreation of an actual reel showing someone singing in the subway, but we haven't located that original reel. We'll acknowledge the creator here once identified.
What song do they sing on the subway?+
"Ain't No Mountain High Enough", the soul duet by Marvin Gaye and Tammi Terrell from 1967, written by Nickolas Ashford and Valerie Simpson; Diana Ross made a well-known recording in 1970. Your Smew AI clip doesn't contain the original recording: it features the vocal performance and train sounds, and you select the song from the audio library when posting.
Is this like the NYC subway singing videos?+
It follows the same concept, performed solo. Actual subway singing has been popular online for years: NYC subway singing clips, the subway singing girl who doesn't realize the whole car hears her, the stranger joining in. This trend is the headphones take on the girl singing on the subway, and the AI creates it from one photo, so you don't need to perform on an actual train.
Is the subway singing video real?+
No, your clip is AI-generated from your photo: the subway car, the headphones, the actions and the voice. No one records you on a train. Keep the platform's AI label visible when posting, and only use your own photo or one from a consenting adult.
Which AI models make the video?+
High-quality AI video models, including Seedance 2.5. Human mode generates directly from your photo; Pet mode first creates an image of your pet in the subway seat with headphones, then converts to video, offering Standard and Best choices. The system selects the optimal available model for each generation.
What prompt does the ain't no mountain high enough ai trend use?+
No creator has published a prompt for it. We began with the prompt shown by one AI template site for the trend (a realistic vertical phone selfie in a mostly empty subway carriage, wired earbuds, closed eyes, lifted chin, one raised hand) and incorporated the key moments from the trend clip plus our tested phrasing that preserves your facial features. You don't write any prompt.
How long is the video and what format is it?+
About 10 seconds, vertical 9:16, as an MP4 with sound and no watermark. Human comes at 720p; Pet comes at 1080p on Standard and 720p on Best.